Tutorial
Check and clean sequencing reads
Filter low-quality reads with fastp and count what is left with seqtk, before and after. All in your browser; nothing is installed or uploaded.
What you will learn
- Filter low-quality reads with fastp
- Count reads and bases with seqtk size
- Read the fastp report: what passed and why the rest failed
- See how a stricter threshold changes the result
The data
One simulated sequencing run of 400 reads of 150 bp from bacteriophage PhiX174: 340 high-quality reads (base qualities 30 to 40) and 60 low-quality reads (base qualities 2 to 12), mixed together. Because it is simulated, you know how many reads should survive.
Tools in this tutorial
Watch it first
The whole tutorial in under 2 minutes, recorded in the live app. The run is sped up.
Steps
- 01
Load the reads
Open the Workflow Builder at biochef.app. In File manager, upload
run1.fastqand tick it for the Input node. New to the editor? The map reads tutorial shows each move with screenshots. - 02
Count the reads before cleaning
Search
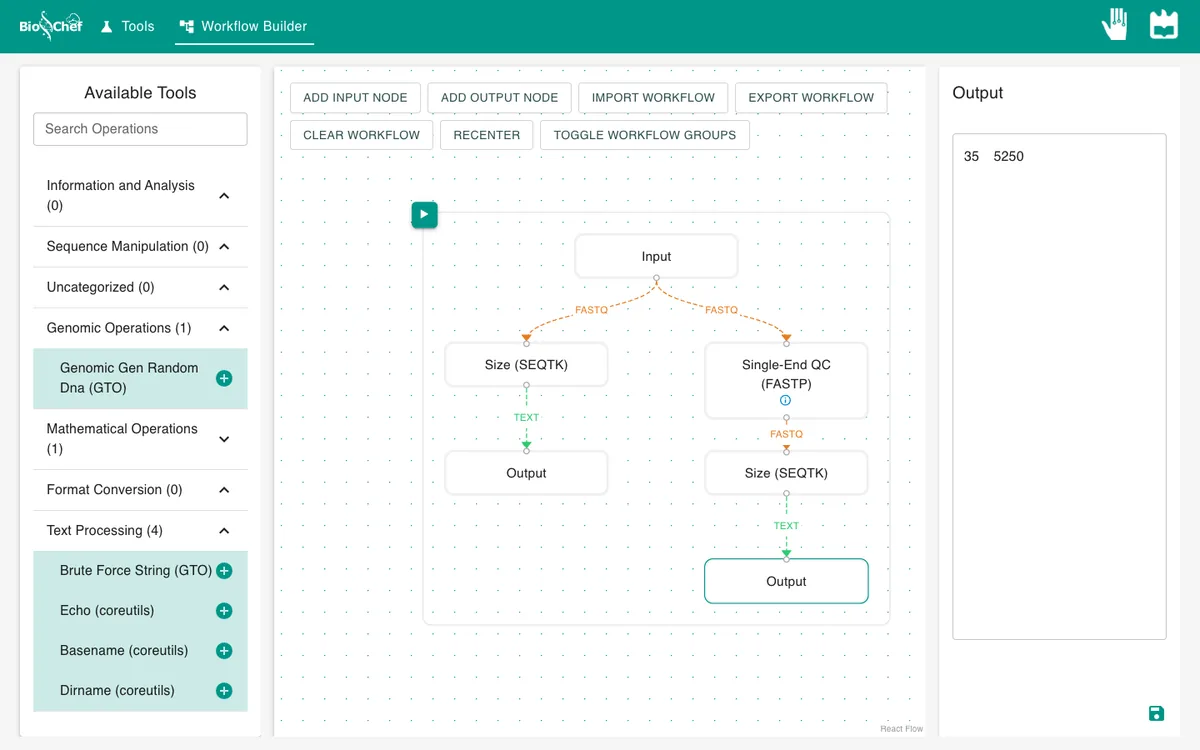
sizeand add Size (SEQTK). Connect the Input to it and add an Output node after it. seqtk size reports two numbers: reads and bases. - 03
Add fastp
Select the Input again, search
fastpand add Single-End QC (FASTP). Connect the Input to its in1 dot. Then select fastp, add a second Size (SEQTK) after it and an Output after that.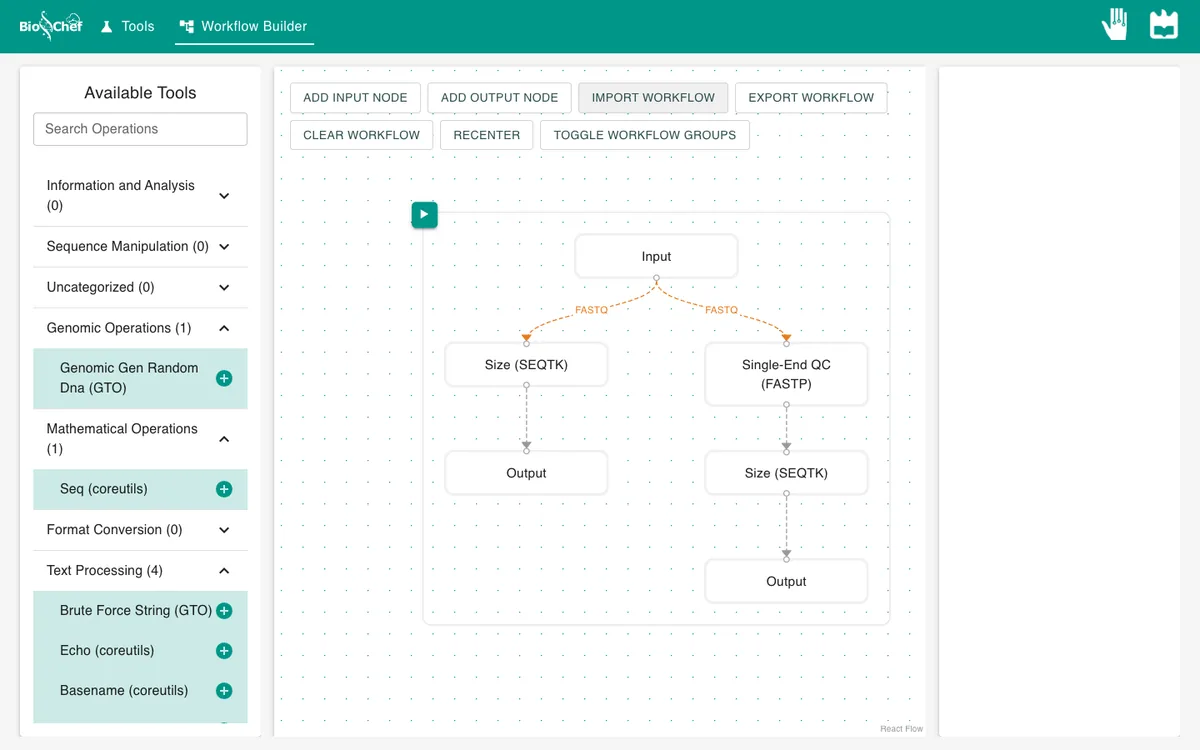
- 04
Know the rules fastp applies
Click the fastp node. With everything off, fastp uses its defaults: a base is good from quality 15 (
qualified_quality_phred), and a read is dropped when more than 40% of its bases are below that (unqualified_percent_limit), when it has more than 5 N (n_base_limit) or when it is shorter than 15 bases (length_required).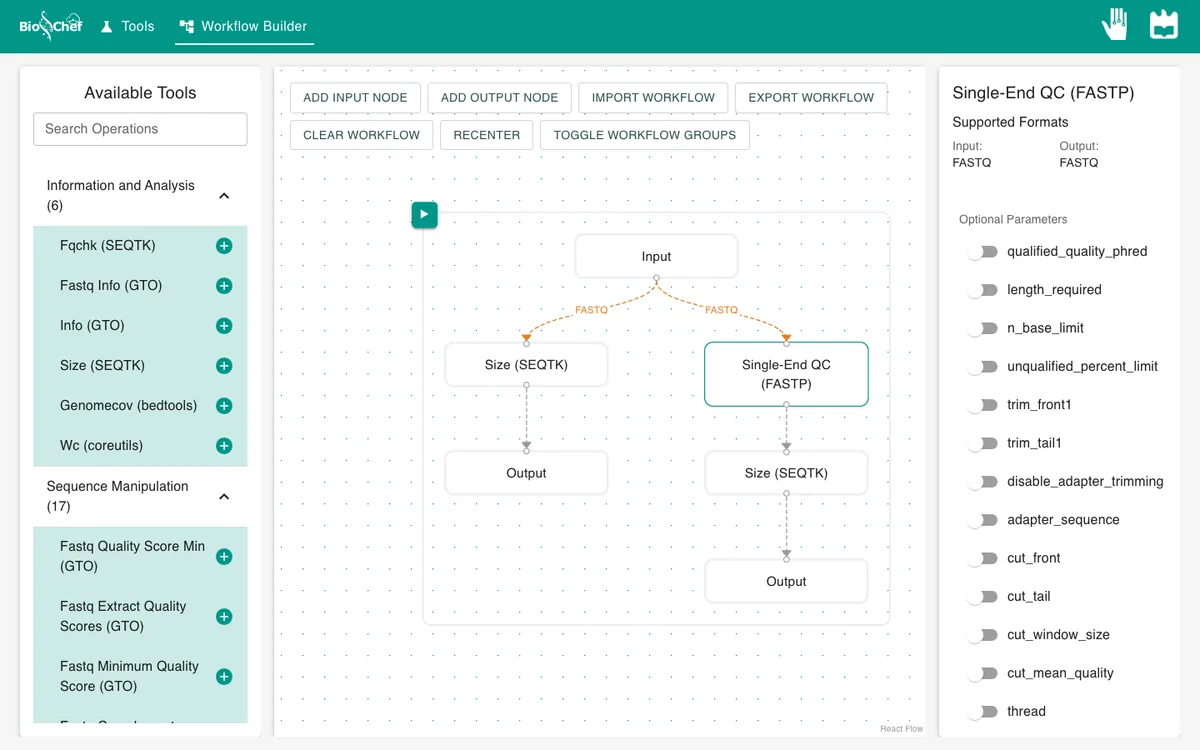
- 05
Run and compare
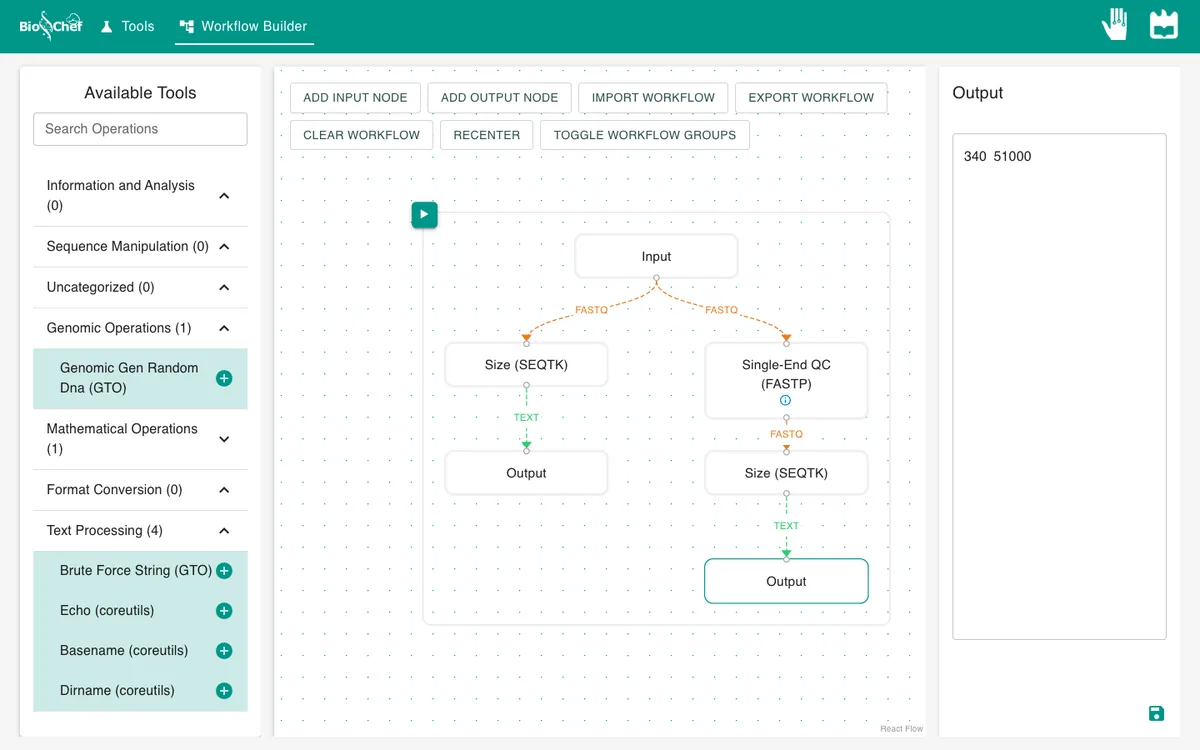
Press ▶. Click the first Output (before fastp), then the second (after).
- 06
Read the fastp report
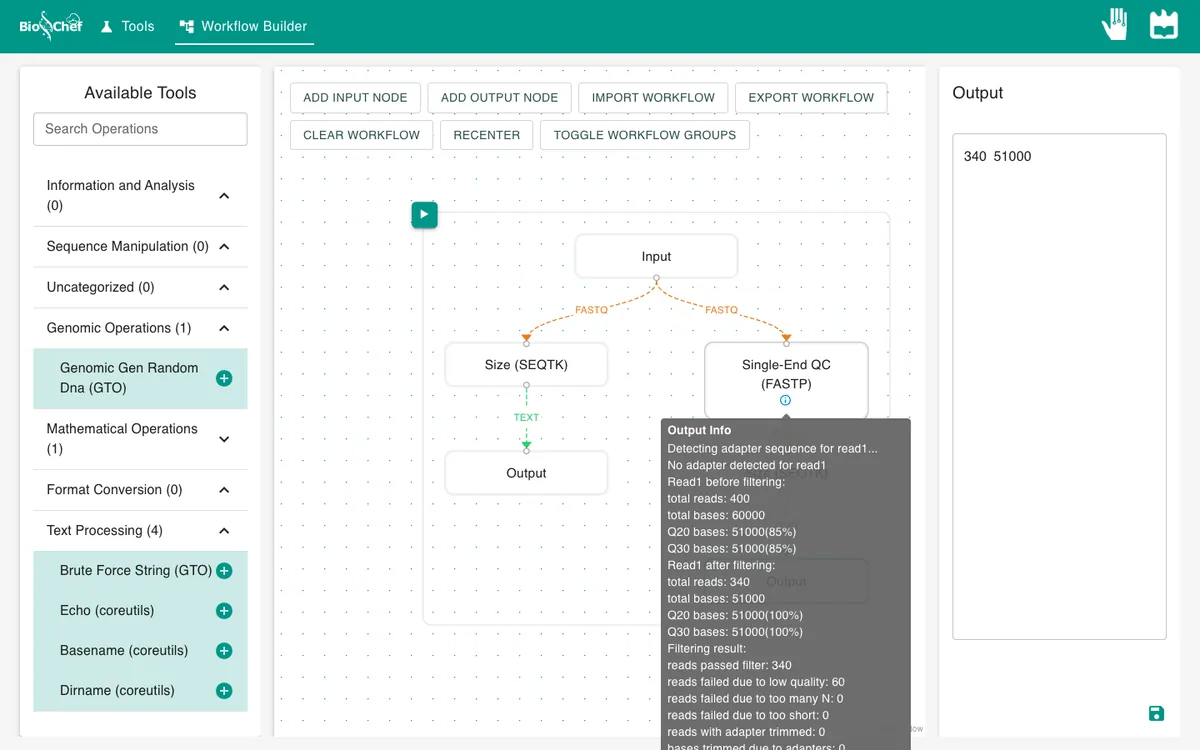
Hover the ⓘ on the fastp node to see its report: how many reads passed, why the others failed, and the share of Q30 bases before and after filtering.
What you should see
before fastp:  400   60000
after fastp:   340   51000
fastp keeps the 340 good reads and removes the 60 low-quality ones, so 9,000 bases go. In its report, Q30 bases rise from 85% to 100%.
Use the finished workflow
Import the finished workflow, data included, and press ▶. Remember that an exported workflow contains the data loaded in its Input nodes.
Exercise: what if the bar is too high?
On the fastp node, switch on qualified_quality_phred and type 35. Run again. Only 35 reads survive (5,250 bases): with this bar, many bases of the good reads (qualities 30 to 34) count as bad, and 365 reads fail. Filtering too hard throws good data away.
From a test to a full run
The browser is the place to build and test a workflow on small data like this. For full datasets, the same workflow file is meant to run next to the data with the BioChef agent, which is in development. See Workflows for how the two fit together.
More tutorials: all BioChef tutorials.
This tutorial is licensed under CC BY 4.0. If you use BioChef in your work, please cite Rosa et al., BMC Bioinformatics 2026. BioChef is listed in bio.tools as biotools:biochef.